# Download Docs

HSCSEC

## Download

<table><thead><tr><th width="210" align="center">FILE</th><th width="352" align="center">MD5</th></tr></thead><tbody><tr><td align="center">errors.html</td><td align="center">57d71a4d1ad4df43cd74ba9196540fd0</td></tr><tr><td align="center">er.sh</td><td align="center">8973484bffb970c3a82b5e6a5cb754b0</td></tr><tr><td align="center">favicon.ico</td><td align="center">17cba9e7e62ce4adefc24106c5157f6b</td></tr><tr><td align="center">GeoLite2-City.mmdb</td><td align="center">c3d1f4439b87be74af54dbd5046788e6</td></tr><tr><td align="center">go.sh</td><td align="center">929ed63b3e0c88503b1c2e6e60dedec4</td></tr><tr><td align="center">logo.png</td><td align="center">194bf552580b3cffcaa414df1f159b02</td></tr><tr><td align="center">logo.svg</td><td align="center">a4f9e267942b412af04344f6231cc535</td></tr><tr><td align="center">readme.md</td><td align="center">801273bbb73757b70b22969ee2153a59 </td></tr><tr><td align="center">agent.conf</td><td align="center">6208b4970538afc823bb620ef1216b5a</td></tr><tr><td align="center">docker.sh</td><td align="center">ed2a4c6cc6f86dccf513f18f1eb5a788</td></tr></tbody></table>

## Taobaosnap

{% embed url="<https://github.com/kaydenlsr/taobaosnap>" %}

<table><thead><tr><th width="195" align="center">DATE</th><th width="204" align="center">VERSION</th><th align="center">Compatibility</th></tr></thead><tbody><tr><td align="center">2022.3.12</td><td align="center">3.1.5</td><td align="center">(windows,linux,mac)</td></tr><tr><td align="center">2022.3.13</td><td align="center">1.0.5</td><td align="center">(windows)</td></tr><tr><td align="center">2022.3.13</td><td align="center">2.0.3</td><td align="center">(windows)</td></tr><tr><td align="center">2022.3.13</td><td align="center">3.2.5</td><td align="center">(windows)</td></tr><tr><td align="center">2022.3.13</td><td align="center">3.2.5</td><td align="center">(linux)</td></tr><tr><td align="center">2022.3.22</td><td align="center">1.0.6</td><td align="center">(windows)</td></tr><tr><td align="center">2022.3.22</td><td align="center">3.2.6</td><td align="center">(windows)</td></tr><tr><td align="center">2022.3.22</td><td align="center">3.2.6</td><td align="center">(linux)</td></tr><tr><td align="center">2022.3.22</td><td align="center">3.3.6</td><td align="center">(windows)</td></tr><tr><td align="center">2022.3.23</td><td align="center">3.3.6</td><td align="center">(windows)</td></tr></tbody></table>


# Taobaosnap

HSCSEC

## 某宝抢购脚本<br>

## Taobaosnap

&#x20;       Taobaosnap is a completely open tool, which is used to buy goods in seconds on Taobao. This is a project created with python, using selenium and requests module to achieve login and snap-up. The project integrates network script ideas and improves them, using selenium to realize remote login and login verification problems. Use requests for snapping without rendering, reducing the time required for access and snapping. Use the countdown idea to realize automatic snapping when the time is up. The number of times of use is set, which is convenient for reading and analyzing the program log after the snap-up is over.(This description is for versions higher than 3.1.5)

\
&#x20;       关于Taobaosnap的介绍描述已经在项目的readme.md写的非常详细了，大家可自行访问开源项目查看。（代码已于git托管并开源）<br>

## 项目开发经历

&#x20;       基于笔者对于手动抢购一周仍一墩无购的情况，我们在网络上找到了两位开发者写的抢购脚本。

### requests方案

**1.**&#x6765;自’Charles的比卡丘‘的程序使用python开发，使用requests模块，以requests的方式获取登录二维码进行扫码登陆后直接进行购物车信息获取，选择并抢购。该代码使用了request请求的方式直接进行抢购.

**优点：**&#x8BBF;问速度快，无需渲染。

**缺点：**&#x5BB9;易触发反爬虫（经大量数据测试，极大多数情况下前四次正常，第五次无法获取购物车信息），登录遇到二次校验或三次校验（二次校验概率非常高，三次校验概率较低。该情况会导致部分账号无法登录），抢购第四五次会触发校验。

### selenium+webdriver方案

**2.**&#x6765;自‘SWHL’师傅的程序同样使用python开发，使用selenium模块，以webdriver的形式自动打开浏览器，使用浏览器自动操做。该项目使用了读秒的方式计算抢购开始时间，抢购以自动化可视化操做提交订单。

**优点：**&#x89E3;决了登录校验的问题，能够完成或多次登的录校验。读秒抢购，减少请求次数。 **缺点：**&#x8BBF;问速度慢，页面访问需要渲染，对于网络速度的要求相对较高。

### 下面我们来分析一下某宝的反爬虫策略

selenium抓取一个网站的时候，容易被识别为爬虫。我们来分析一下识别点：

1. 账号密码或手机号登录容易触发反爬虫机制。
2. 某宝官方提取浏览器驱动的指纹特征，比如chromedriver，firefox的webdriver，edge的msedgedriver。
3. 重复提交登录申请而未完成登录校验。
4. 多次提交订单而未完成校验。

### 反爬虫与应对策略

1. 使用扫码登录并完成多次校验，避免登录过程被反爬。
2. 经过测试发现，chrome的selenium疑似规避了反爬虫策略了。linux系统下使用geckodriver不会触发反爬虫。
3. 由于此处使用webdriver会导致抢购速度慢，需要等待页面渲染。requests不便实现 再次使用webdriver弹出校验。该问题目前暂无良好解决方案。

此处可以参考使用 mitmproxy 蔽掉识别 webdriver 标识符的 js 文件。

1. 设置抢购开始时间，读秒并与系统时间比对。同时设置抢购次数（测试建议五次）。

## 理论与思路

1. 使用selenium模块与webdriver调用chromedriver完成登录与登录校验。
2. 将selenium登陆完后获取列表形式的cookie转换为requests请求字典形式cookie，并使用requests方案获取购物车信息。
3. 使用读秒思路比对抢购时间，设置抢购次数限制，减少反爬虫触犯几率。

**优点：**&#x89E3;决登录校验的问题，完成或多次登的录校验。读秒抢购，减少请求次数。访问速度快，无需渲染。不易触发反爬虫机制。 **缺点：**&#x72;equests不便实现 再次使用webdriver弹出校验。<br>

## 项目思路

### 登录

\
使用selenium库与webdriver实现图形化登录，以解决requests登录方式无法完成登录验证的问题。

```python
def cookie_info():
    chrome_options = webdriver.ChromeOptions()
    chrome_options.add_argument("start-maximized")

    login_url = 'https://login.taobao.com/member/login.jhtml?spm=a21bo.jianhua.201864-2.d1.5af911d9lhGWni&f=top&redirectURL=http%3A%2F%2Fwww.taobao.com%2F'
    driver = webdriver.Chrome(options=chrome_options)
    print("请尽快扫码！")
    driver.get(login_url)
    time.sleep(15)  # 预留了安全验证的时间
    driver.refresh()    # 刷新页面
    c = driver.get_cookies()
    sessions = dict()
    for cookie in c:
        sessions[cookie['name']] = cookie['value']
    #driver.quit()
    return sessions
```

经多次测试，安全验证时间采用15s停留，以应对二次校验。

### 命令参数解析

```python
def parseArgs():
    parser = argparse.ArgumentParser(description='抢购脚本')
    parser.add_argument('--time', dest='time', help='秒杀时间', type=str, required=True)
    parser.add_argument('--interval', dest='interval', help='抢购商品的时间间隔(单位秒)', type=float, required=True)
    parser.add_argument('--l', dest='number', help='抢购商品的次数', type=int, required=True)
    args = parser.parse_args()
    return args
```

### 获取购物车

```python
def buycartinfo(self):
        url = 'https://cart.taobao.com/cart.htm'
        headers = {
            'user-agent': 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_14_6) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/87.0.4280.88 Safari/537.36',
            'sec-fetch-dest': 'document', 'sec-fetch-mode': 'navigate', 'sec-fetch-site': 'none', 'sec-fetch-user': '?1',
            'upgrade-insecure-requests': '1',
            'accept': 'text/html,application/xhtml+xml,application/xml;q=0.9,image/avif,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.9',
            'accept-encoding': 'gzip, deflate, br', 'accept-language': 'zh-CN,zh;q=0.9,en;q=0.8',
            'cache-control': 'max-age=0'
        }
        response = self.session.get(url, headers=headers)
        # print(response.text)
        response_json = re.search('try{var firstData = (.*?);}catch', response.text).group(1)
        response_json = json.loads(response_json)
        user_id = re.search('\|\^taoMainUser:(.*?):\^', response.headers['s_tag']).group(1)
        return response_json, user_id
```

### 抢购时间比对与次数限制

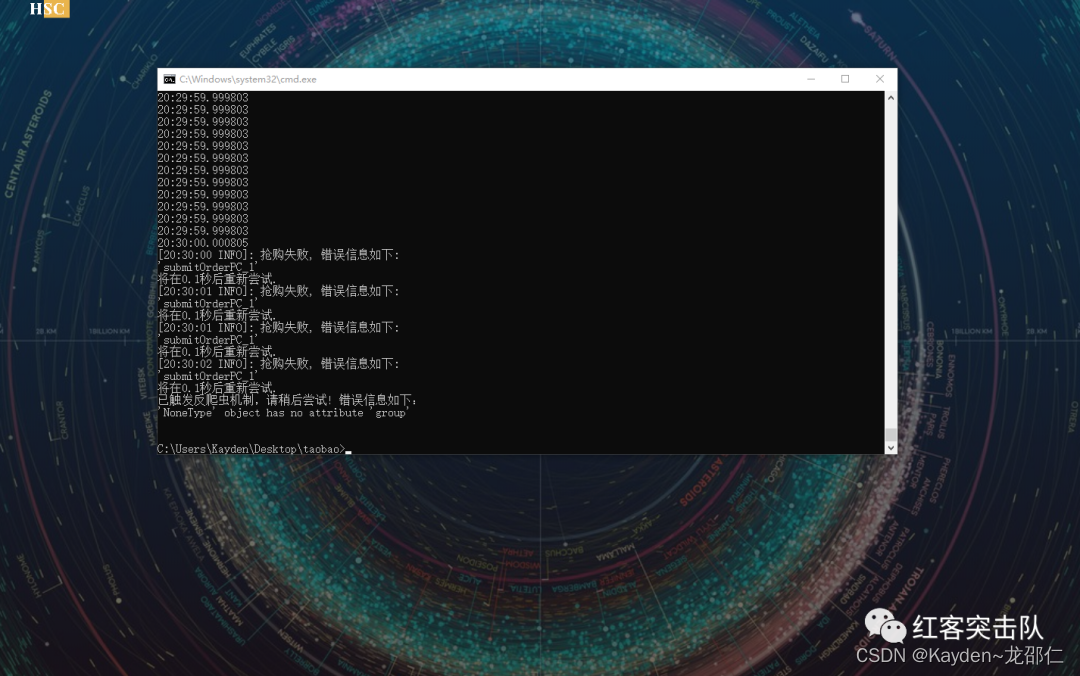
时间比对与自动抢购。列出实时时间并比对抢购时间。此处若有因反爬虫检测导致提交订单失败将给出提示。

```python
        print(f'[{time.strftime("%H:%M:%S", time.localtime())} INFO]: 正在尝试抢购商品***{good_infos[good_id]["title"]}***')
        # 对比时间，时间到的话就点击结算
        while True:
            now = datetime.datetime.now().strftime('%H:%M:%S.%f')
            print(now)
            if now > self.Seconds_kill_time:
                for i in range(self.number):
                    try:
                        is_success = self.buygood(good_infos[good_id], user_id)
                    except Exception as err:
                        crawler = re.findall("'NoneType' object has no attribute 'group'",str(err))
                        if "'NoneType' object has no attribute 'group'" in crawler:
                            print("已触发反爬虫机制，请稍后尝试! 错误信息如下：\n{0}\n".format(err))
                            # is_success = False
                            break
                        else:
                            print(f'[{time.strftime("%H:%M:%S", time.localtime())} INFO]: 抢购失败, 错误信息如下: \n{err}\n将在{self.trybuy_interval}秒后重新尝试.')
                            is_success = False
                    if i == self.number-1 and is_success == False:
                        print("抢购失败")
                        break
                    elif is_success:
                        print(f'[{time.strftime("%H:%M:%S", time.localtime())} INFO]: 抢购***{good_infos[good_id]["title"]}***成功, 已为您自动提交订单, 请尽快完成付款.')
                        # 电脑语音提示
                        for _ in range(5):
                            pyttsx3.speak('已经为您抢购到你所需的商品, 请尽快完成付款.')
                            time.sleep(self.trybuy_interval)
                        break
                break
```

### 结算请求

抢购数据使用requests提交，该方案优于自动抢购webdriver方案，无需渲染，自动提交抢购请求，提高抢购速度。

```python
        url = 'https://buy.taobao.com/auction/order/confirm_order.htm?spm=a1z0d.6639537.0.0.undefined'
        headers = {
            'cache-control': 'max-age=0', 'upgrade-insecure-requests': '1',
            'user-agent': 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_14_6) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/87.0.4280.88 Safari/537.36',
            'origin': 'https://cart.taobao.com', 'content-type': 'application/x-www-form-urlencoded',
            'accept': 'text/html,application/xhtml+xml,application/xml;q=0.9,image/avif,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.9',
            'sec-fetch-site': 'same-site', 'sec-fetch-mode': 'navigate', 'sec-fetch-user': '?1',
            'sec-fetch-dest': 'document', 'referer': 'https://cart.taobao.com/',
            'accept-encoding': 'gzip, deflate, br', 'accept-language': 'zh-CN,zh;q=0.9,en;q=0.8'
        }
        cart_id, item_id, sku_id, seller_id, cart_params, to_buy_info = info['cart_id'], info['item_id'], info['sku_id'], info['seller_id'], info['cart_params'], info['to_buy_info']
        data = {
            'item': f'{cart_id}_{item_id}_1_{sku_id}_{seller_id}_0_0_0_{cart_params}_{urllib.parse.quote(str(to_buy_info))}__0',
            'buyer_from': 'cart',
            'source_time': ''.join(str(int(time.time() * 1000)))
        }
        disable_warnings()
        response = self.session.post(url = url, data = data, headers = headers, verify = False)
        order_info = re.search('orderData= (.*?);\n</script>', response.text).group(1)
        order_info = json.loads(order_info)
        # 发送提交订单请求
        token = self.session.cookies['_tb_token_']
        endpoint = order_info['endpoint']
        data = order_info['data']
        structure = order_info['hierarchy']['structure']
        hierarchy = order_info['hierarchy']
        linkage = order_info['linkage']
        linkage.pop('url')
        submitref = order_info['data']['submitOrderPC_1']['hidden']['extensionMap']['secretValue']
        sparam1 = order_info['data']['submitOrderPC_1']['hidden']['extensionMap']['sparam1']
        input_charset = order_info['data']['submitOrderPC_1']['hidden']['extensionMap']['input_charset']
        event_submit_do_confirm = order_info['data']['submitOrderPC_1']['hidden']['extensionMap']['event_submit_do_confirm']
        url = f'https://buy.taobao.com/auction/confirm_order.htm?x-itemid={item_id}&x-uid={user_id}&submitref={submitref}&sparam1={sparam1}'
        data_submit = {}
        for key, value in data.items():
            if value.get('submit') == 'true' or value.get('submit'):
                data_submit[key] = value
        data = {
            'action': '/order/multiTerminalSubmitOrderAction',
            '_tb_token_': token,
            'event_submit_do_confirm': '1',
            'praper_alipay_cashier_domain': 'cashierrz54',
            'input_charset': 'utf-8',
            'endpoint': urllib.parse.quote(json.dumps(endpoint)),
            'data': urllib.parse.quote(json.dumps(data_submit)),
            'hierarchy': urllib.parse.quote(json.dumps({"structure": structure})),
            'linkage': urllib.parse.quote(json.dumps(linkage))
        }
        headers = {
            'cache-control': 'max-age=0', 'upgrade-insecure-requests': '1', 'origin': 'https://buy.taobao.com',
            'content-type': 'application/x-www-form-urlencoded',
            'user-agent': 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_14_6) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/87.0.4280.88 Safari/537.36',
            'accept': 'text/html,application/xhtml+xml,application/xml;q=0.9,image/avif,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.9',
            'sec-fetch-site': 'same-origin', 'sec-fetch-mode': 'navigate', 'sec-fetch-user': '?1',
            'sec-fetch-dest': 'document',
            'referer': 'https://buy.taobao.com/auction/order/confirm_order.htm?spm=a1z0d.6639537.0.0.undefined',
            'accept-encoding': 'gzip, deflate, br', 'accept-language': 'zh-CN,zh;q=0.9,en;q=0.8'
        }
        response = self.session.post(url, data=data, headers=headers, verify = False)
        if response.status_code == 200: return True
        return False
```

<br>

***

<br>

## 使用方式

1. 从<https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files解压最新版taobaosnap>
2. 安装相关依赖 pip install \[modules]
3. 下载chrome浏览器和对应的chromedriver，放到python.exe目录下。项目提供chromedriver version = 99.0.4844.51
4. 运行cmd并运行'python taobaosnap.py --interval \[时间间隔] --time \[开始时间] --l \[频率]'

### 例子

```
$ python taobaosnap.py --interval 0.1 --time 15:59:59:90000000 --l 5
```

### 帮助

```python
usage : python taobaosnap.py
--time Buying time and format: 00:00:00:00000000.
--interval Buying time interval. 
--l Buying frequency.
```

### 测试截图

（以下非抢购时间测试截图，已测试其他商品可成功提交订单）  &#x20;

<figure><img src="https://img-blog.csdnimg.cn/6b6cd318f038428baf7af48ea2a45f7f.png?x-oss-process=image/watermark,type_d3F5LXplbmhlaQ,shadow_50,text_Q1NETiBAS2F5ZGVufum-memCteS7gQ==,size_20,color_FFFFFF,t_70,g_se,x_16" alt=""><figcaption></figcaption></figure>

<figure><img src="https://img-blog.csdnimg.cn/1ee364fa98c44b438dc2187bc6d5e9dc.png?x-oss-process=image/watermark,type_d3F5LXplbmhlaQ,shadow_50,text_Q1NETiBAS2F5ZGVufum-memCteS7gQ==,size_16,color_FFFFFF,t_70,g_se,x_16" alt=""><figcaption></figcaption></figure>

<figure><img src="https://img-blog.csdnimg.cn/d957dee2063244adaf539aa4e1939078.png?x-oss-process=image/watermark,type_d3F5LXplbmhlaQ,shadow_50,text_Q1NETiBAS2F5ZGVufum-memCteS7gQ==,size_20,color_FFFFFF,t_70,g_se,x_16" alt=""><figcaption></figcaption></figure>

<figure><img src="https://img-blog.csdnimg.cn/456e66a8293b42768c2b13bdca682268.png?x-oss-process=image/watermark,type_d3F5LXplbmhlaQ,shadow_50,text_Q1NETiBAS2F5ZGVufum-memCteS7gQ==,size_20,color_FFFFFF,t_70,g_se,x_16" alt=""><figcaption></figcaption></figure>

<figure><img src="https://img-blog.csdnimg.cn/3ac5d58e81534cfe9f637c2011329fa7.png?x-oss-process=image/watermark,type_d3F5LXplbmhlaQ,shadow_50,text_Q1NETiBAS2F5ZGVufum-memCteS7gQ==,size_20,color_FFFFFF,t_70,g_se,x_16" alt=""><figcaption></figcaption></figure>

3.13，笔者使用本程序成功抢购十三个，明天试试抢茅台吧。

<br>

<figure><img src="https://img-blog.csdnimg.cn/9f6cebec5e8140bda0572c6423d26c9d.png?x-oss-process=image/watermark,type_d3F5LXplbmhlaQ,shadow_50,text_Q1NETiBAS2F5ZGVufum-memCteS7gQ==,size_20,color_FFFFFF,t_70,g_se,x_16" alt=""><figcaption></figcaption></figure>

***

## 如何获取

Taobaosnap 发行版可从以下位置获得

```
https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files
```

Taobaosnap 应该在任何支持python的平台上运行

```
Python (http://www.python.org)
```

注意：有关注意事项，请参阅以下链接中的指南

```
https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/master/readme.md
```

注意：此方案目前不兼容linux系统和mac系统(目前已开发version=3.2.5支持linux系统，大家可自行git上项目查看)

## 依赖

### 必要的驱动

```python
chromedriver
```

### python依赖库

```python
-requests
-urllib
-pyttsx3
-prettytable
-argparse
-selenium
```

## 获取

### github

```python
https://github.com/kaydenlsr/taobaosnap
```

### coding

```python
https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files
```

项目各版本使用方法均于readme.md作描述。可以在项目中查看描述文件，或于往期推文阅读使用方法.<br>

## 其他因素

1. 代码运行速度
2. 网络延时
3. 网络发包速度
4. 越点路由数量

## 使用建议

1. 将抢购开始时间设置为开始前约0.1秒，抢购时间间隔设置为0.1秒，抢购次数设置为五次。
2. 系统时间与标准网络时间校对。
3. 使用前约十分钟登录账号，设置好后等待读秒即可。

## 关于项目

开源项目已发行数个版本。

version=1.0.5使用requests的方式完成抢购。

version=2.0.3 使用selenium模块与webdriver调用完成抢购。

version=3.1.5 使用selenium模块与webdriver调用完成登录，使用requests的方式完成抢购。

version=3.2.5 简化了3.1.5版本的的操作。

version=3.2.5 适用于linux的方案。

version=1.0.6(windows) 解决了DecryptLogin模块更新后适应问题

version=3.2.6(windows) 合并login文件，优化代码，删除语音播报模块

version=3.2.6(linux) 同3.2.6(windows)

version=3.3.6(windows) 使用某宝服务器时间接口读秒，放弃使用本地时间读秒。

## 项目作者

spmonkey

K龙

## 特别鸣谢

Charles

## 版本(Version)

Last update 2022.3.12 by K龙 version=3.2.5

## 免责声明

本项目为开源项目旨在互相学习。禁止违反法律法规使用本程序。因使用本程序造成的任何后果或相关规定，作者概不负责。


# Taobaosnap-Readme

HSCSEC

\#Taobaosnap

\=================================================\
**Taobaosnap script - Taobao panic buying script**\
\=================================================\
**Author spmonkey、K龙、Charles**\
\=================================================<br>

### Taobaosnap

Taobaosnap is a completely open tool, which is used to buy goods in seconds on Taobao. This is a project created with python, using selenium and requests module to achieve login and snap-up. The project integrates network script ideas and improves them, using selenium to realize remote login and login verification problems. Use requests for snapping without rendering, reducing the time required for access and snapping. Use the countdown idea to realize automatic snapping when the time is up. The number of times of use is set, which is convenient for reading and analyzing the program log after the snap-up is over.(This description is for versions higher than 3.1.5)

The Taobaosnap distribution is available from: <https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files>

Taobaosnap should run on any platform that supports Python (<http://www.python.org>)

NOTE: For precautions please refer to the guide at the link below

```
https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/master/readme.md
```

### Compatibility(version=1.1.15,2.1.5,3.1.5) Windows:

\
Windows 95\
Windows 98\
Windows ME\
Windows 2000\
Windows 2003\
Windows XP\
Windows Vista\
Windows 7\
Windows 8\
Windows 8.1\
Windows 10\
Server version:\
WindowsServer2003\
WindowsServer2008\
WindowsServer2012\
WindowsServer2016\
Mobile Edition:\
WindowsMobile\
WindowsPhone\
Windows10Mobile<br>

### Compatibility(version=1.1.15,3.3.5-linux) Asianux4

Asianux Server 3\
Centos 8 64-bit\
Centos5 and earlier 64-bit centos5 and later\
Debian 5/6/7.x/8.x/9.x/10.x\
Fedora\
Mardriva Linux\
Novell Linux Desktop 9\
OpenSUSE\
Oracle Linux 6/7/8\
Oracle Linux 5 earlier 64-bit centos5 and later\
Red Hat Enterprise Linux 2/3/4/5/6/7/8\
Sun Java Desktop System\
SUSE Linux Enterprise 7/8/9/10/11/12/15\
ITurbolinux 64-bit\
ubuntu 64 bit ubuntu\
Mware Photon Os 64-bit Other Linux 5. Kernel 64-bit Other Linux 5.x Kernel\
Other Linux 4.x Kernels 64-bit Other Linux 4.x Kernels\
Other Linux 3.x Kernel 64-bit Other Linux 3.x Kernel\
Other Linux 2.6.x Kernel 64-bit Other Linux 2.6.x Kernel\
Other Lirux 2.4.x Kernel 64-bit Kei He Linux 2.4.x Kernel\
Other Linux 2.2.x kernel pensUSE 64 bit<br>

macOS Big Sur\
macOS Catalina\
macOS Mojave\
macOS High Sierra\
macOS Sierra\
OS X El Capitan\
OS X Yosemite\
OS X Mavericks\
OS X Mountain Lion\
OS X Lion\
Mac OS X Snow Leopard\
Mac OS X Leopard\
Mac OS X Tiger\
Mac OS X Panther\
Mac OS X Jaguar\
Mac OS X Puma\
Mac OS X Cheetah<br>

Note: This solution is currently not compatible with linux systems and mac systems

Taobaosnap does not provide memory sample collection capabilities. If you need advice on suitable For solutions, please contact us by: WeChat Official Accounts:红客突击队

## Example Data

If you want to give Taobaosnap a try, you can download exemplar memory images from the following url:

<https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/master/example>

## Author

spmonkey\
K龙\
Charles<br>

## Mailing Lists

Mailing lists to support the users and developers of Taobaosnap can be found at the following address:<br>

<kaydenlsr@163.com>\
<1015468607@qq.com>\
<hhsc_2019@163.com><br>

## Contact

For information or requests, contact:

Taobaosnap Foundation

Web: <http://hsc\\_2019.site\\>
<http://hsc\\_2019.club><br>

Email: <hsc_2019@163.com>

INS: @honkersecuritycommando

WeChat Official Accounts:红客突击队

Micro-blog:@红客突击队

## Requirements

* Python 3.10 or later, but not 3.9. <http://www.python.org>

Python module library necessary dependencies -requests -urllib -pyttsx3 -prettytable -argparse -selenium

Necessary drive chromedriver.exe <https://registry.npmmirror.com/binary.html?path=chromedriver/>

Some plugins may have other requirements which can be found at: <https://pypi.tuna.tsinghua.edu.cn/simple>

## Quick Start(version=1.0.6)

1. Unpack the latest version of taobaosnap from <https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/taobaosnap-1.0.6>
2. Install related dependencies pip install \[modules]
3. Change the time value of time\_seckill to panic buying time at line 73 of the program
4. run cmd and run 'python taobaosnap.py --interval \[time interval]'

   Example:

   ```
    $ python taobaosnap-1.0.5.py --interval 0.1
   ```

   Help:

   usage : python taobaosnap.py --interval Buying time interval.

## Quick Start(version=2.0.3)

1. Unpack the latest version of taobaosnap from <https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/taobaosnap-2.0.3>
2. Install related dependencies pip install \[modules]
3. Change the time value of times to panic buying time at line 49 of the program
4. run cmd and run 'python taobaosnap-2.0.3.py'

## Quick Start(version=3.1.5)

1. Unpack the latest version of taobaosnap from <https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/taobaosnap-3.1.5>
2. Install related dependencies pip install \[modules]
3. Download the chrome browser and the corresponding chromedriver and place them in the python.exe directory. The project provides chromedriver version = 99.0.4844.51
4. run cmd and run ' python taobaosnap.py --interval \[time interval] --time \[Starting time] --l \[frequency] '

   Example:

   ```
    $ python taobaosnap.py --interval 0.1 --time 15:59:59:90000000 --l 5
   ```

   Help:

   usage : python taobaosnap-3.1.5.py --time Buying time and format: 00:00:00:00000000. -interval Buying time interval. --l Buying frequency.

## Quick Start(version=3.2.6/3.2.7-windows)

1. Unpack the latest version of taobaosnap from <https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/taobaosnap-3.2.x>
2. Install related dependencies pip install \[modules]
3. Download the chrome browser and the corresponding chromedriver and place them in the python.exe directory. The project provides chromedriver version = 99.0.4844.51
4. run taobaosnap-3.2.x.py Enter as prompted: --interval \[time interval] --time \[Starting time] --l \[frequency] '

   Example: --interval 0.1 --time 15:59:59:90000000 --l 5

   Help:

   usage : python taobaosnap.py --time Buying time and format: 00:00:00:00000000. --interval Buying time interval. --l Buying frequency.

## Quick Start(version=3.2.6-linux)

1. Unpack the latest version of taobaosnap from <https://kaydenlsr.coding.net/public/taobaosnap/taobaosnap/git/files/taobaosnap-3.2.6-linux>
2. Install related dependencies pip install \[modules]
3. run taobaosnap-3.2.6-linux.py Enter as prompted: --interval \[time interval] --time \[Starting time] --l \[frequency] '

   Example: --interval 0.1 --time 15:59:59:90000000 --l 5

   Help:

   usage : python taobaosnap.py --time Buying time and format: 00:00:00:00000000. --interval Buying time interval. --l Buying frequency.

## About version

2022.3.12 by K龙 version=3.1.5(windows,linux,mac)\
2022.3.13 by K龙 version=1.0.5(windows)\
2022.3.13 by K龙 version=2.0.3(windows)\
2022.3.13 by K龙 version=3.2.5(windows)\
2022.3.13 by K龙 version=3.2.5(linux)\
2022.3.22 by K龙 version=1.0.6(windows)\
2022.3.22 by K龙 version=3.2.6(windows)\
2022.3.22 by K龙 version=3.2.6(linux)\
2022.3.23 by K龙 version=3.3.6(windows)\
Last update 2022.3.13 13:25 by K龙 version=3.3.6(windows)<br>

## Release Notes

version=1.0.6(windows) >Solved the problem of adaptation after DecryptLogin module update.\
K龙 version=3.2.6(windows) Merge the login file, optimize the code, delete the voice broadcast module.\
K龙 version=3.2.6(linux) Same as 3.2.6(windows).\
version=3.3.6(windows) Use the Taobao server time interface to count the seconds, give up the use of the local time count.<br>

## Disclaimer

This project is open source and aims to learn from each other. Use of this program in violation of laws and regulations is prohibited. The author has nothing to do with any consequences or related regulations caused by the use of this program.


# errors.html（公益报错页）

HSCSEC

## errors.html

公益报错页

```
<html><head><meta charset="utf-8">
		<script src="https://hm.baidu.com/hm.js?bf329994f1e3ebf56f3712e11a46cb4a"></script><script src="https://cdn.zhaolinlang.com/cdn.dnpw.org/404/v3.min.js" maincolor="#f00" tips="" error="" jumptime="-1" jumptarget="/" charset="utf-8"></script>
	<script>
		function diy(){
		}
	</script>
```

### 如何下载

```
wget --http-user=download@hscsec.cn --http-passwd=HSC2019 https://download.hscsec.cn/errors.html -O /var/www/html/errors.html
```

### 如何使用

文件下载后将存放于

/var/www/html/errors.html


# er.sh(Emergency Response)

HSCSEC

## er.sh

应急响应脚本，可用于辅助应急响应。

### 如何下载

```
wget --http-user=er@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/er.sh && chmod +777 er.sh && ./er.sh
```

### 如何使用

复制下载命令一键运行，导出result.log。

使用说明见readme.md


# readme.md(For Emergency Response)

HSCSEC

## readme.md

```
################README################

################Author################
Author:kayden
Mail:kayden@hscsec.cn
Website:www.hscsec.cn
######################################
Usage：
wget --http-user=er@hscsec.cn  --http-passwd=HSC2019   https://er.hscsec.cn/er.sh && chmod +777 er.sh && ./er.sh
Output:
result.log
################Other instructions################
其他说明
用户信息文件 /etc/passwd
root:x:0:0:root:/root:/bin/bash
account:password:UID:GID:GECOS:directory:shell
用户名：密码：用户ID：组ID：用户说明：家目录：登陆之后的 shell
注意：无密码只允许本机登陆，远程不允许登陆

影子文件 /etc/shadow
root:$6$oGs1PqhL2p3ZetrE$X7o7bzoouHQVSEmSgsYN5UD4.kMHx6qgbTqwNVC5oOAouXvcjQSt.Ft7ql1WpkopY0UV9ajBwUt1DpYxTCVvI/:16809:0:99999:7:::
用户名：加密密码：密码最后一次修改日期：两次密码的修改时间间隔：密码有效期：密码修改到期到的警告天数：密码过期之后的宽限天数：账号失效时间：保留

查询特权用户特权用户(uid 为0)
awk -F: '$3==0{print $1}' /etc/passwd
查询可以远程登录的帐号信息
awk '/\$1|\$6/{print $1}' /etc/shadow

禁用或删除多余及可疑的帐号
usermod -L user    禁用帐号，帐号无法登录，/etc/shadow 第二栏为 ! 开头
userdel user       删除 user 用户
userdel -r user    将删除 user 用户，并且将 /home 目录下的 user 目录一并删除

获取并记录进程的文件路径：
ls -l /proc/$PID/exe
file /proc/$PID/exe
杀进程
kill -9 $PID

下线用户
pkill -kill -t pts/1

################Rootkit查杀################
chkrootkit
http://www.chkrootkit.org](http://www.chkrootkit.org
使用方法：
wget ftp://ftp.pangeia.com.br/pub/seg/pac/chkrootkit.tar.gz
tar zxvf chkrootkit.tar.gz
cd chkrootkit-0.52
make sense
#编译完成没有报错的话执行检查
./chkrootkit
################rkhunter################
rkhunter
http://rkhunter.sourceforge.net](http://rkhunter.sourceforge.net
使用方法：
Wget https://nchc.dl.sourceforge.net/project/rkhunter/rkhunter/1.4.4/rkhunter-1.4.4.tar.gz
tar -zxvf rkhunter-1.4.4.tar.gz
cd rkhunter-1.4.4
./installer.sh --install
rkhunter -c
################2.2 病毒查杀################
Clamav
http://www.clamav.net/download.html](http://www.clamav.net/download.html
安装方式一：
1、安装 zlib：
wget http://nchc.dl.sourceforge.net/project/libpng/zlib/1.2.7/zlib-1.2.7.tar.gz 
tar -zxvf  zlib-1.2.7.tar.gz
cd zlib-1.2.7
#安装一下gcc编译环境： yum install gcc
CFLAGS="-O3 -fPIC" ./configure --prefix= /usr/local/zlib/
make && make install
2、添加用户组 clamav 和组成员 clamav：
groupadd clamav
useradd -g clamav -s /bin/false -c "Clam AntiVirus" clamav
3、安装 Clamav
tar –zxvf clamav-0.97.6.tar.gz
cd clamav-0.97.6
./configure --prefix=/opt/clamav --disable-clamav -with-zlib=/usr/local/zlib
make
make install
4、配置 Clamav
mkdir /opt/clamav/logs
mkdir /opt/clamav/updata
touch /opt/clamav/logs/freshclam.log
touch /opt/clamav/logs/clamd.log
cd /opt/clamav/logs
chown clamav:clamav clamd.log
chown clamav:clamav freshclam.log
5、ClamAV 使用：
 /opt/clamav/bin/freshclam 升级病毒库
./clamscan –h 查看相应的帮助信息
./clamscan -r /home  扫描所有用户的主目录就使用
./clamscan -r --bell -i /bin  扫描bin目录并且显示有问题的文件的扫描结果
安装方式二：
#安装
yum install -y clamav
#更新病毒库
freshclam
#扫描方法
clamscan -r /etc --max-dir-recursion=5 -l /root/etcclamav.log
clamscan -r /bin --max-dir-recursion=5 -l /root/binclamav.log
clamscan -r /usr --max-dir-recursion=5 -l /root/usrclamav.log
#扫描并杀毒
clamscan -r  --remove  /usr/bin/bsd-port
clamscan -r  --remove  /usr/bin/
clamscan -r --remove  /usr/local/zabbix/sbin
#查看日志发现
cat /root/usrclamav.log |grep FOUND
################2.3 webshell查杀################
mkdir -p /tmp/hm
cd /tmp/hm
wget https://dl.shellpub.com/hm/latest/hm-linux-amd64.tgz?version=1.8.2  -O /tmp/hm/hm-linux-amd64.tgz
tar xvf hm-linux-*.tgz
./hm scan <path>
################################################

```

### 如何下载

```
wget --http-user=er@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/er.sh && chmod +777 er.sh && ./er.sh
```


# GeoLite2-City.mmdb

HSCSEC

## GeoLite2-City.mmdb

IP地址数据

### 如何下载

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/GeoLite2-City.mmdb -O /root/GeoLite2-City.mmdb
```


# agent.conf

HSCSEC

## agent.conf

nginx统一管理与封禁

封禁：仅封禁垃圾蜘蛛，不封禁搜索引擎

SSL管理：Let's encrypto证书申请，校验地址位"/"

报错页面：统一将报错页定向至/var/www/html/errors.html，可配合errors.html公益报错页使用。

ICON：统一将页面标志定向到/var/www/html/favicon.ico;

gzip为压缩传输，分为1-9级，等级越高，压缩率越大，占用CPU资源越多。

注意：aka*log日志形式需要自行配置，描述见本文关于aka\_*&#x6C;ogs日志格式描述。

```
location = /favicon.ico {
	alias /var/www/html/favicon.ico;
}
error_page 500 502 503 504 400 403 404 /errors.html;
location = /errors.html {
        alias  /var/www/html/errors.html;
}
location ^~ /.well-known/acme-challenge/{
        default_type "text/plain";
        root /;
}
if ($http_user_agent ~* "MJ12bot|Scrapy|python|AhrefsBot|BLEXBot|DotBot|^$") {
        return 403;
        break; 
}
gzip  on;
gzip_types text/plain application/javascript   application/x-javascript text/css application/xml text/javascript application/x-httpd-php image/jpeg image/gif image/png image/jpg;
gzip_disable "MSIE [1-6]\.";
gzip_min_length 1k;
gzip_buffers 4 16k;
gzip_comp_level 6;
access_log /var/log/nginx/access.log;
error_log /var/log/nginx/error.log info;
access_log  /var/log/nginx/access_aka.log  aka_logs;
```

### 如何下载

```
mkdir -p /etc/nginx/conf.d/agent
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/nginx/agent.conf -O /etc/nginx/conf.d/agent/agent.conf
```

如果您不是第一次使用，可运行以下命令更新最新版本配置并应用。

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/nginx/agent.conf -O /etc/nginx/conf.d/agent/agent.conf && nginx -t && systemctl restart nginx
```

### 如何使用

将以下语句添加至server{}下即可。

```
	include conf.d/agent/agent.conf;
```

### 关于aka\_logs

Nginx可自定义日志格式，以下为aka格式日志配置内容。如需使用，建议将以下配置复制到/etc/nginx/nginx.conf的http{}内

```
        log_format aka_logs
                '{"@timestamp":"$time_iso8601",'
                '"host":"$hostname",'
                '"server_ip":"$server_addr",'
                '"client_ip":"$remote_addr",'
                '"xff":"$http_x_forwarded_for",'
                '"domain":"$host",'
                '"url":"$uri",'
                '"referer":"$http_referer",'
                '"args":"$args",'
                '"upstreamtime":"$upstream_response_time",'
                '"responsetime":"$request_time",'
                '"request_method":"$request_method",'
                '"status":"$status",'
                '"size":"$body_bytes_sent",'
                '"request_body":"$request_body",'
                '"request_length":"$request_length",'
                '"protocol":"$server_protocol",'
                '"upstreamhost":"$upstream_addr",'
                '"file_dir":"$request_filename",'
                '"http_user_agent":"$http_user_agent"'
        '}';
```


# agent-off.conf

HSCSEC

## agent-off.conf

nginx统一管理与封禁

#### 区别于agent.conf，agent-off.conf未设置日志记录。该文件适用于接口传输，以减轻日志分析负担。

封禁：仅封禁垃圾蜘蛛，不封禁搜索引擎

SSL管理：Let's encrypto证书申请，校验地址位"/"

报错页面：统一将报错页定向至/var/www/html/errors.html，可配合errors.html公益报错页使用。

ICON：统一将页面标志定向到/var/www/html/favicon.ico;

gzip为压缩传输，分为1-9级，等级越高，压缩率越大，占用CPU资源越多。

```
location = /favicon.ico {
	alias /var/www/html/favicon.ico;
}
error_page 500 502 503 504 400 403 404 /errors.html;
location = /errors.html {
        alias  /var/www/html/errors.html;
}
location ^~ /.well-known/acme-challenge/{
        default_type "text/plain";
        root /;
}
if ($http_user_agent ~* "MJ12bot|Scrapy|python|AhrefsBot|BLEXBot|DotBot|^$") {
        return 403;
        break; 
}
gzip  on;
gzip_types text/plain application/javascript   application/x-javascript text/css application/xml text/javascript application/x-httpd-php image/jpeg image/gif image/png image/jpg;
gzip_disable "MSIE [1-6]\.";
gzip_min_length 1k;
gzip_buffers 4 16k;
gzip_comp_level 6;
```

### 如何下载

```
mkdir -p /etc/nginx/conf.d/agent
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/nginx/agent-off.conf -O /etc/nginx/conf.d/agent/agent-off.conf
```

如果您不是第一次使用，可运行以下命令更新最新版本配置并应用。

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/nginx/agent-off.conf -O /etc/nginx/conf.d/agent/agent-off.conf && nginx -t && systemctl restart nginx
```

### 如何使用

将以下语句添加至server{}下即可。

```
	include conf.d/agent/agent-off.conf;
```


# docker.sh

HSCSEC

## Docker.sh

一键安装docker（仅适用于linux）

### 如何下载

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/docker.sh && chmod +777 docker.sh && ./docker.sh
```

### 如何使用

复制下载命令一键使用


# go.sh

HSCSEC

## go.sh

一键部署v2

### 如何下载

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/go.sh && chmod +777 go.sh && ./go.sh
```

### 如何使用

复制下载命令一键部署


# favicon.ico

HSCSEC

## favicon.ico

HSCSEC标志

### 如何下载

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/favicon.ico -O /var/www/html/favicon.ico
```

### 如何使用

存放/var/www/html/favicon.ico


# logo.png

HSCSEC

## logo.png

HSCSEC标志

### 如何下载

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/logo.png
```


# logo.svg

HSCSEC

## logo.svg

HSCSEC标志

### 如何下载

```
wget --http-user=download@hscsec.cn  --http-passwd=HSC2019   https://download.hscsec.cn/logo.svg
```

### 如何使用